2026-11-16
Introducing explicit prompt caching with open-weight models on Amazon Bedrock
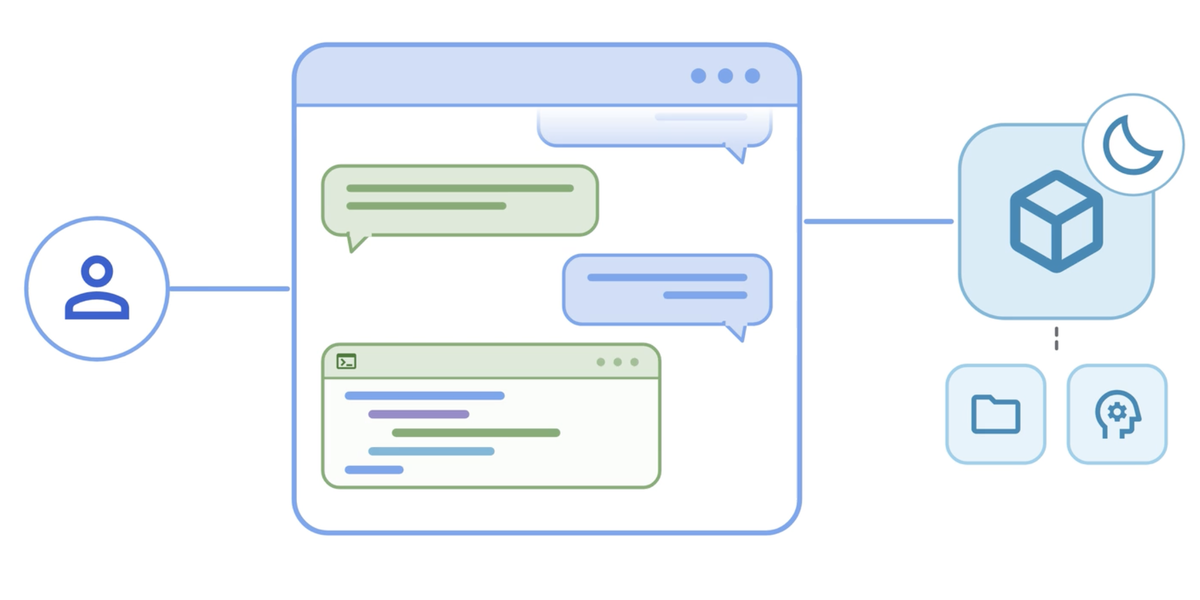
Many generative AI applications resend the same long context on every request. Prompt caching lets open-weight models on Amazon Bedrock reuse it to reduce input cost and latency.